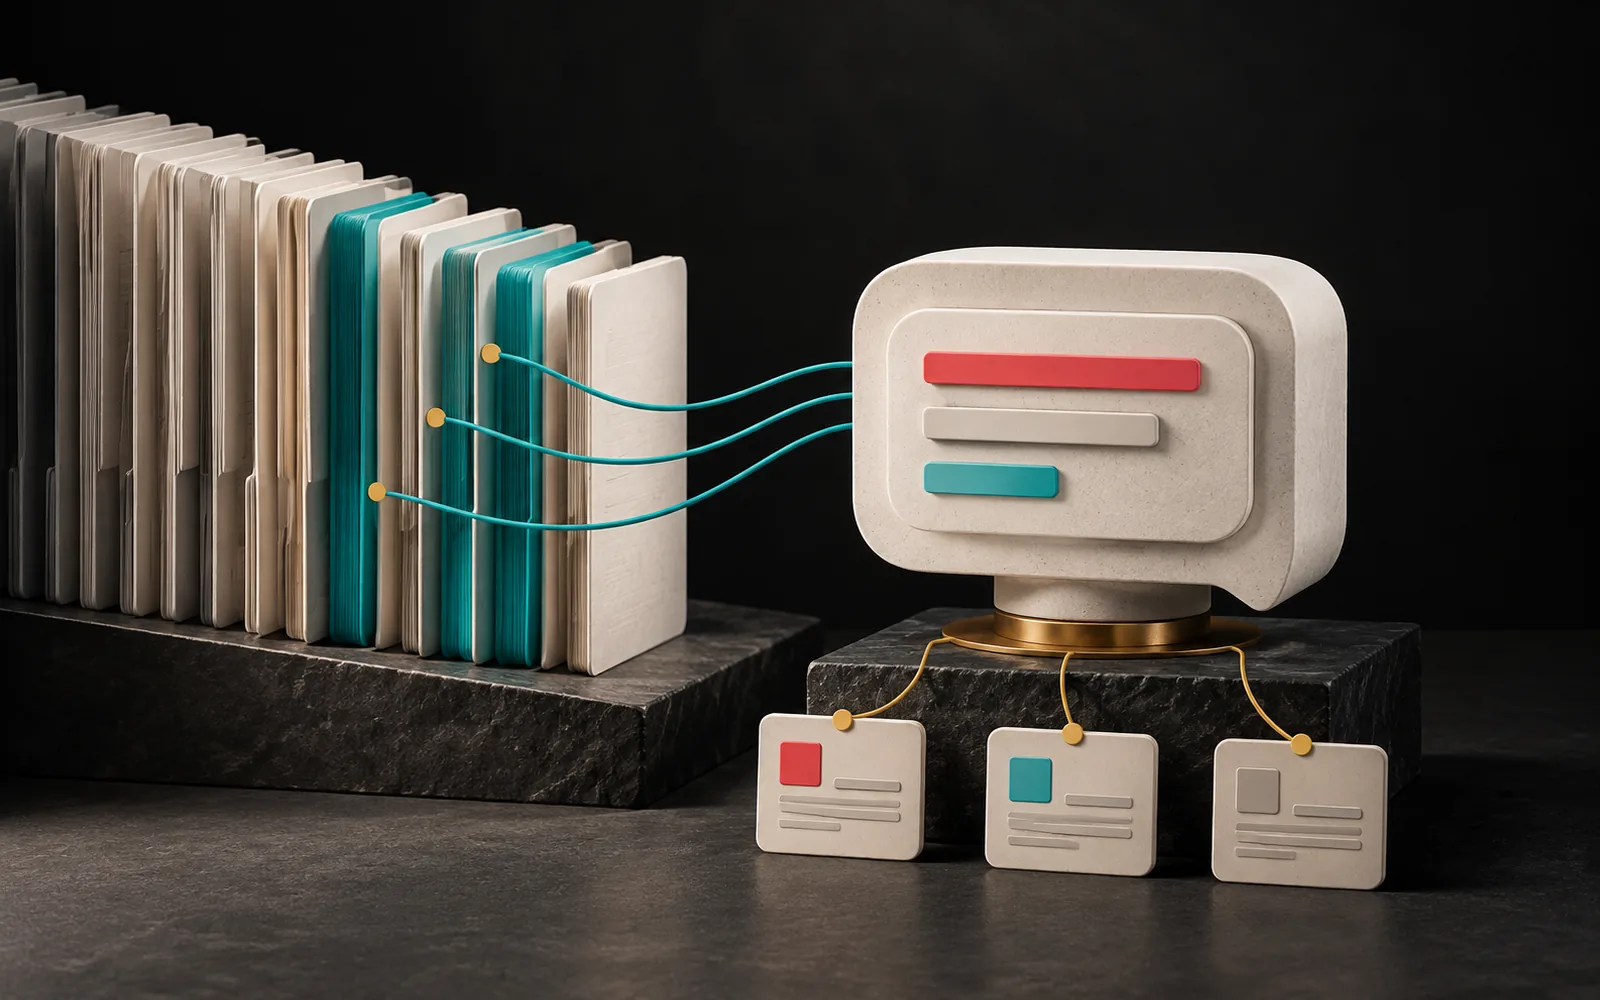
RAG (Retrieval-Augmented Generation) is a method in which an AI model searches your documents before answering a question and bases its answer on the relevant passages it finds. Nobody retrains the model. Instead, the system "places the right information in front of it" with every question. That is why RAG is often the first method that comes to mind for assistants that work with corporate knowledge such as internal procedures, product manuals or FAQs. In this post, we explain what RAG is, how it differs from fine-tuning, and what to watch out for under Turkey's Personal Data Protection Law (PDPL, Law No. 6698) when you use your own data.
In short
- An LLM is a language model that learned from general knowledge. It doesn't automatically know information specific to your company.
- RAG finds the document passages relevant to a question and gives them to the model at answer time. Updating the document is enough to update the knowledge.
- Fine-tuning suits a different goal: making a model's behavior, format and tone consistent. For new and frequently changing information, teams usually prefer RAG.
- RAG can reduce hallucinations but doesn't eliminate them. Bad or outdated documents mean bad answers.
- For documents containing personal data, you must design access permissions, cross-border transfers and deletion requests in from the start.
Core concepts
LLM (large language model): A model trained on a very large amount of text that can understand and generate text. It doesn't know information that wasn't in its training data (your pricing policy, your internal procedure, the manual you updated last week). Where it doesn't know, it may produce an answer that looks reasonable but is wrong. People call this a "hallucination."
Context: The text given to the model along with a question. The model produces its answer based both on what it learned in training and on this context. The core idea of RAG is to find and supply the right context automatically.
Embedding (vector representation): A method that turns the meaning of a text into a list of numbers. Texts that are close in meaning have numeric representations that are close to each other too. That way, the question "how do I get a refund on an invoice?" can match a paragraph titled "paperwork for returned products," even if they share no words.
Vector database: A database that stores these numeric representations and quickly answers the question "which passages are closest in meaning to this question?"
Fine-tuning: In the definition used in the generative AI guide of the Turkish Data Protection Authority (KVKK), further training a foundation model for a specific task through supervised learning. In other words, the model itself changes.
The idea behind RAG isn't new. The term became widespread with the 2020 paper "Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks" by Patrick Lewis and colleagues. The paper proposed combining the knowledge stored in a model's parameters with an external, searchable document index.
How does RAG work?
RAG has two stages.
Preparation (once, and whenever documents change):
- First, you collect the documents: PDF manuals, procedures, FAQs, product pages.
- Next, the system splits the documents into meaningful chunks (e.g., by heading or paragraph).
- Then it calculates an embedding for each chunk and saves it in the vector database. Alongside it, the database keeps details such as which document the chunk came from and who may see it.
Question time (for every question):
- The system also converts the user's question into an embedding.
- It then finds the chunks closest to the question in the database. During this step, it filters out chunks the user has no permission to see.
- Next, it gives the chunks it found to the model along with the question: "Answer based only on the information below; if you're not sure, say you don't know."
- The model produces the answer. A good system also shows which documents the answer is based on.
RAG or fine-tuning?
OpenAI's guide to optimizing model accuracy positions the two methods as solutions to different problems:
- If the model lacks knowledge (the information is outdated, company-specific or changes often), improving the context, that is, methods such as RAG, is the right fit.
- If the model has the knowledge but does the job inconsistently (wrong format, varying tone, skipped steps), fine-tuning is the right fit. The goal is consistent behavior.
- The two are not alternatives to each other. In fact, you can use them together when needed.
| Question | RAG | Fine-tuning |
|---|---|---|
| What changes? | The context given to the model | The model itself |
| Best suited for | Company-specific, current or frequently changing information | A fixed format, tone or task behavior |
| Updating knowledge | Update the document and re-index it | Requires retraining |
| Citing sources | Easy: the answer is based on specific chunks | Hard: the knowledge is spread throughout the model |
| Access permissions | Can be applied per document or per chunk | Hard to separate by permission once it's in the model |
| Deleting data | You can delete the document or chunk from the index | Making a model "forget" information is still a research topic |
| Preparation effort | Document organization and search quality | High-quality training examples and evaluation |
The "forgetting" row in the table is especially important. A comprehensive survey of machine "unlearning" published in 2025 notes that some methods may only suppress the model's behavior rather than truly deleting the information, and that verifying deletion is still an open problem. So when you may need to delete personal data, RAG is more manageable.
The limits of RAG
RAG is a powerful method, but it isn't magic:
- Document quality: If there are contradictory, outdated or incomplete documents, the system will confidently pass them on. RAG doesn't fix disorganized information; it makes it visible.
- Retrieval errors: If the search misses the right chunk, the model answers with incomplete context. Chunking and search settings directly affect the quality of the results.
- Hallucinations don't disappear entirely: The model may still add information that isn't in the chunks it received. Citing sources and being able to say "I don't know" matter.
- Hidden instructions in documents: OWASP states that RAG and fine-tuning do not fully remove the risk of prompt injection. Hidden text in a document that enters the knowledge base can influence the model's behavior. Therefore, documents should come from trusted sources, and someone should check them before they enter the system.
- Vector database risks: In OWASP's 2025 list, vector and embedding weaknesses are a separate entry. The main risks: unauthorized data leakage through weak access control, different groups sharing the same database accessing each other's data, and attackers adding deliberately corrupted data to the knowledge base. Chief among the recommended measures are permission-aware retrieval and logical separation of data.
Data privacy and the PDPL
If your corporate knowledge base contains customer correspondence, staff information or service records, your RAG system is processing personal data. The main points from the generative AI guide published by the Personal Data Protection Authority (KVKK) in November 2025, and from the general principles:
- Scope of the law: Processing personal data with generative AI systems falls under the PDPL. General principles such as lawfulness, accuracy, purpose limitation and proportionality apply here too.
- Data minimization: Only put the documents needed for the purpose into the knowledge base. A product FAQ assistant doesn't need access to customer correspondence. Where possible, strip personal data out of documents or anonymize it.
- Cross-border transfers: If the embedding service, vector database or language model runs at a provider abroad and personal data goes there, then, as the guide also stresses, the transfer must comply with Article 9 of the PDPL and the regulation on cross-border transfers published in July 2024. We explained the general logic of cloud services in our cloud computing post.
Notices, roles, deletion and logging
- Privacy notices: The guide recommends informing people separately and clearly about processing carried out to use an AI system and processing carried out to develop the system and its models.
- Roles: You should assess separately, for each processing activity, whether the service provider is a data processor acting on your behalf or a data controller for its own purposes. Also check in the contract whether the provider uses your data to train its models.
- Accuracy and deletion: Update documents containing outdated or incorrect information, and delete or anonymize data whose retention period has ended. In RAG, this also means removing the document from the index.
- Logging and security: Log who asked which question and which documents the system accessed. Because these logs may themselves contain personal data, you must protect them too.
We covered the general principles on the software side in detail in our post on PDPL-compliant software development.
Where to start with a corporate knowledge base
- Pick a single use case. For example, "the technical service team finding answers in product manuals."
- Collect and clean up the documents. Weed out old versions and resolve contradictions. This is often the step that takes longest.
- Define the access rules. Who can see which document? Build these rules into the system from the start.
- Map the data flow. Which data goes to which service, and to which country? Base your PDPL assessment on this map.
- Prepare test questions. Try the system with 20–30 questions whose answers you know. Check whether it cites sources and whether it can say "I don't know."
- Collect user feedback. Wrong answers show which document is missing or incorrect.
You can also connect a knowledge base to an AI agent as a tool. In that case, the principles on agent permission limits from our AI agents post apply as well.
Our experience
In our own products, data separation and access permissions are not features we add later; they are part of the architecture. AquaCRM, which we developed for water treatment service companies, is a subscription-based SaaS product, and each subscribing company works in its own isolated data space. The same principle applies to a RAG system: one company's or one user's documents must never come back as the answer to someone else's question.
We approach corporate knowledge base projects in this order: first the document organization and access rules, then an assessment of the data flow under the PDPL, and last the choice of model and tools. You can always swap the model. However, the document organization and permission design are the foundation of the system.
Frequently asked questions
Do we need to train our own AI model for RAG?
No. The advantage of RAG is that you can use an existing model with your own documents without retraining it. What you need is to organize the documents, make them searchable and connect them to the model correctly.
Is uploading files to a general-purpose assistant the same as RAG?
The logic can be similar: the assistant can search the file you upload and base its answer on it. The difference is that in a corporate RAG system, the documents, access permissions, the data's storage location and the logs are under your control. Before uploading documents containing personal data to a general-purpose assistant, check the tool's data policy.
Does RAG completely prevent hallucinations?
No, but it can reduce them. When the model answers based on the document passages it receives, it is less likely to produce wrong information. Even so, you need to show the source of the answer, make sure it says "I don't know" when it isn't sure, and check critical answers.
When is fine-tuning needed?
Fine-tuning is worth considering when the model has the right knowledge but can't do the job consistently in the way you want; for example, if it needs to produce a particular report format with the same structure every time. However, to teach the model new or frequently changing information, RAG is usually the better fit.
Conclusion
RAG is one of the most practical ways to use AI with your own data: the model doesn't change, the knowledge comes from your documents, answers can cite sources, and updating a document is enough to update the knowledge. Fine-tuning, on the other hand, makes behavior consistent rather than adding knowledge. Whichever you choose, what determines success usually comes before the model: how you organize your documents, the access rules, and processing personal data in line with the PDPL.
If you are planning a knowledge base or assistant that works on your own documents, take a look at our software & digital solutions service, or contact us. For the broader uses of AI in business, you can also read our post on AI for business.
This article is for general information only and is not legal advice.
Sources7
- Lewis et al., "Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks", arXiv:2005.11401 (2020) arxiv.org
- OpenAI, "Optimizing LLM accuracy" (which problems RAG and fine-tuning solve) developers.openai.com
- Personal Data Protection Authority (KVKK), "Guide on Generative AI and the Protection of Personal Data (in 15 Questions)" (Üretken Yapay Zekâ ve Kişisel Verilerin Korunması Rehberi), November 2025 kvkk.gov.tr
- PDF text of the same guide (definition of fine-tuning, cross-border transfers, privacy notices, data controller and data processor roles) kvkk.gov.tr
- OWASP GenAI Security Project, "LLM01:2025 Prompt Injection" genai.owasp.org
- OWASP GenAI Security Project, "LLM08:2025 Vector and Embedding Weaknesses" genai.owasp.org
- Ren et al., "SoK: Machine Unlearning for Large Language Models", arXiv:2506.09227 (June 2025) arxiv.org